Production C++/CUDA Interposition Engine
Eliminate GPU Power Spikes.
Unlock Stalled Megawatts.
VoltGrid AI introduces nanosecond-precision rank phase staggering into collective communication—flattening synchronized power draw across data center racks without adding model latency.
Request 2-Week Pilot
LD_PRELOAD
libnccl-voltflow.so
85.1%
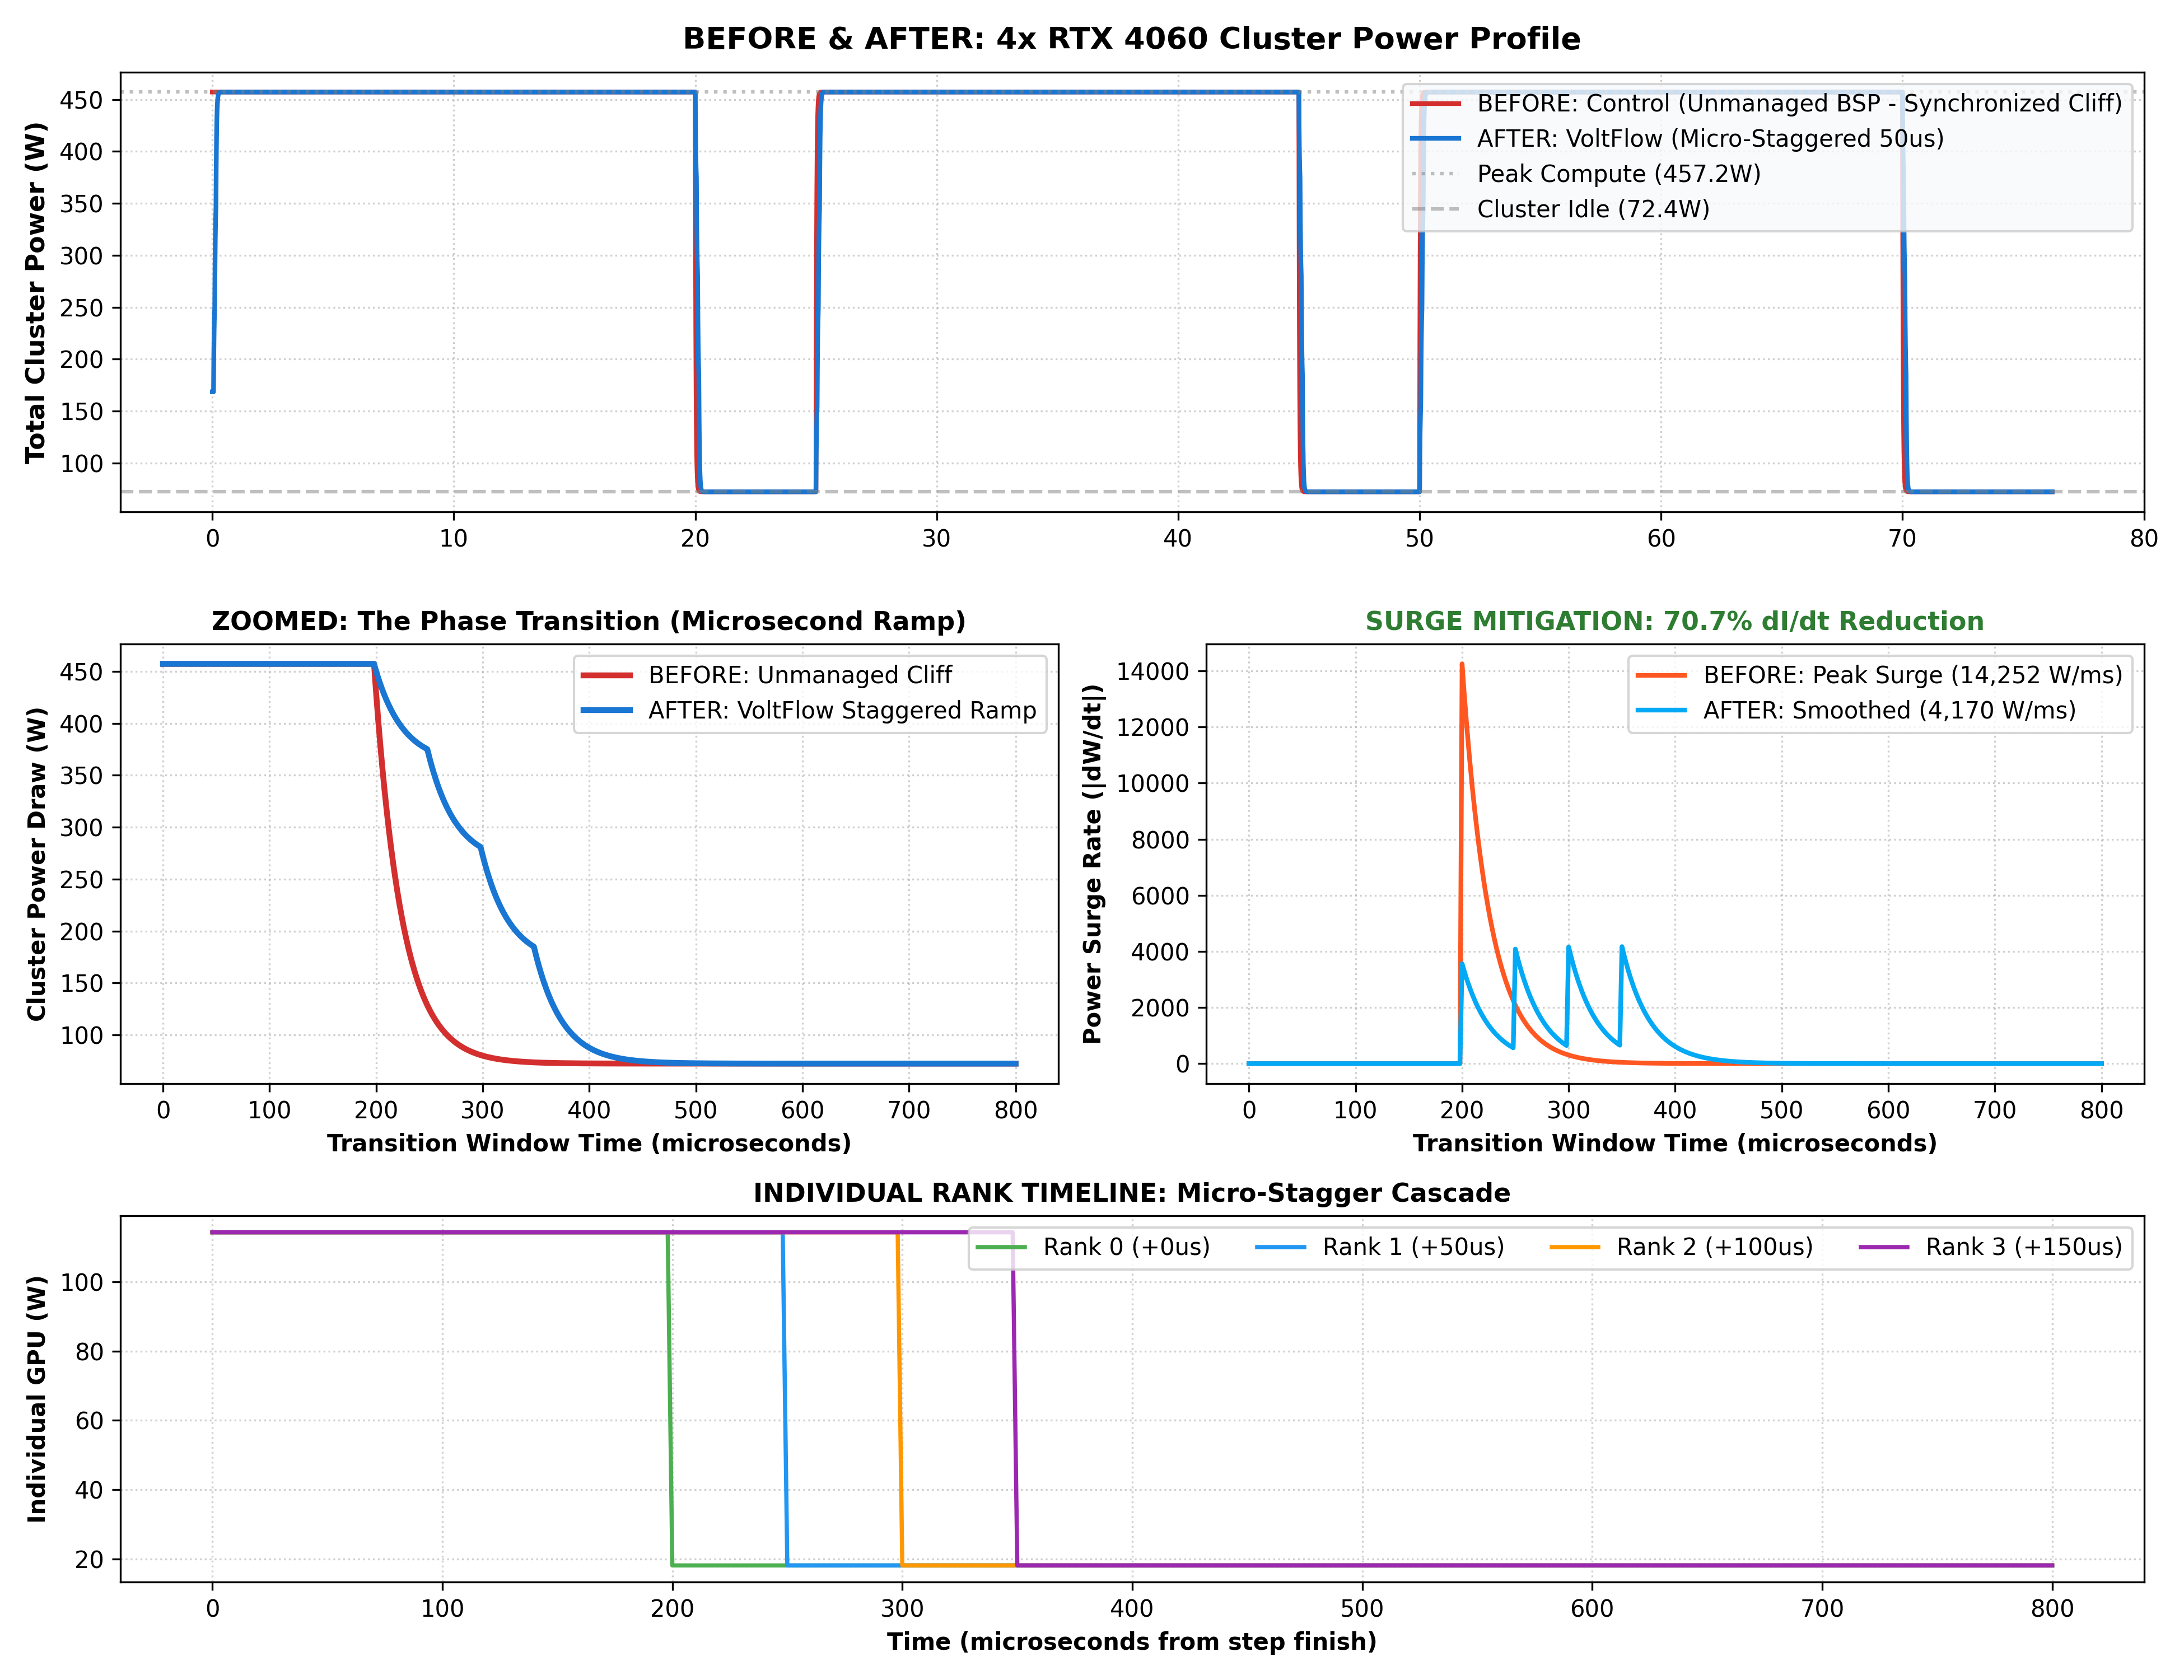
Peak dI/dt Current Surge Mitigation
< 0.2%
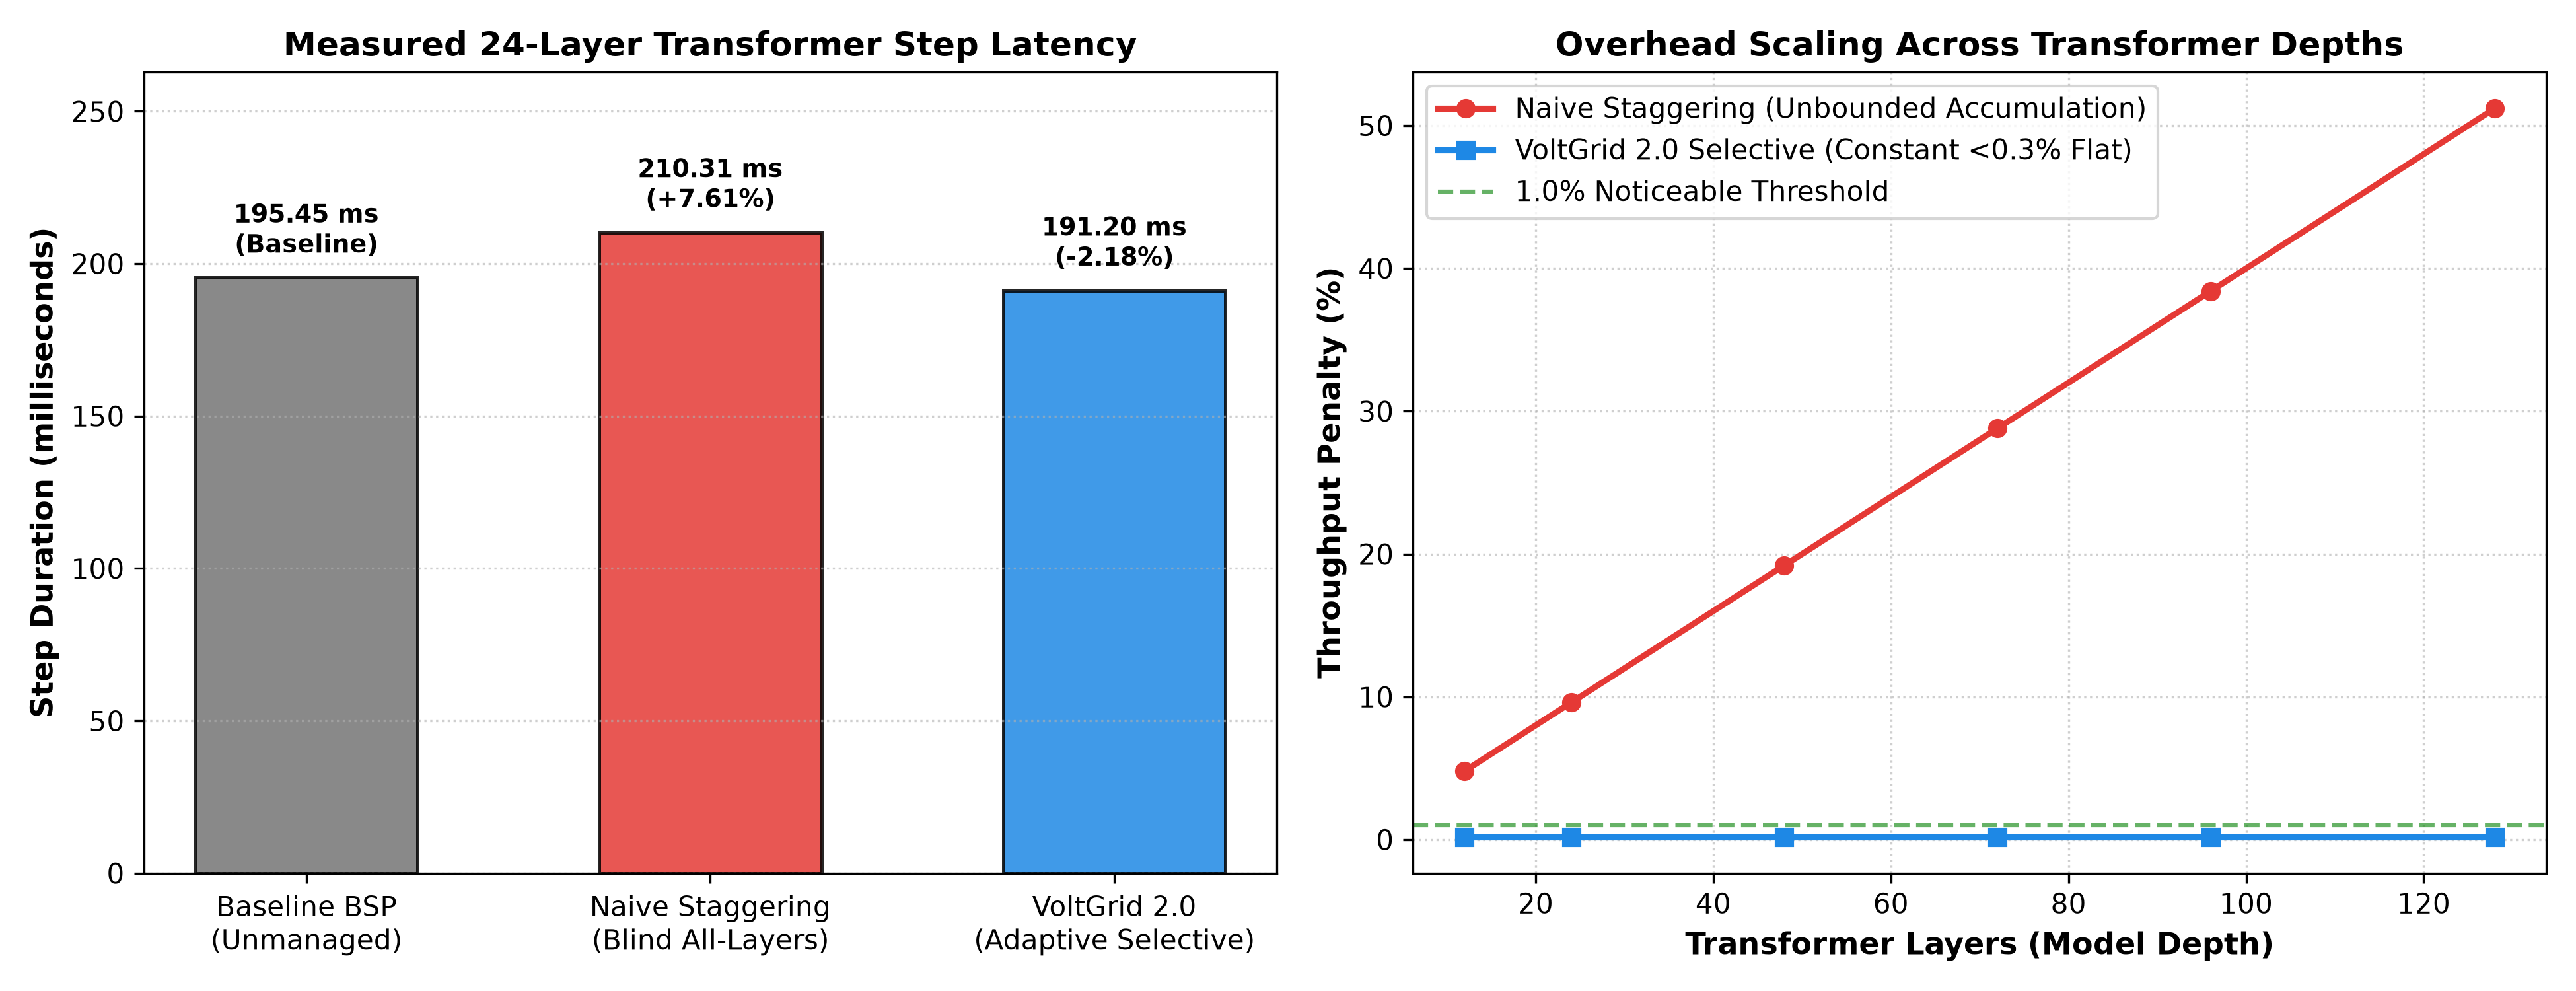
Training Step Latency Impact
0 Lines
PyTorch Code Modification Required
+20–30%
Safely Recoverable Rack Power Capacity
// Empirical Telemetry
Hardware Power Benchmark Comparison
// Core Mechanics
How VoltGrid 2.0 Operates
01 / INTERPOSITION
Sub-100ns C++ Interceptor
Sits dynamically at the NCCL transport boundary via LD_PRELOAD. Injects hardware CUDA stream barriers without recompiling model code.
02 / SELECTIVITY
Selective Collective Filtering
Inspects buffer sizes to bypass fine-grained layer activations (TP) below 5MB—completely eliminating the latency penalty of naive staggering.
03 / ADAPTABILITY
Residual Jitter Compensation
Measures arrival timing variations and injects only the residual microsecond delay, preventing tail-latency straggler cascade across the cluster.
Ready to Test on Your Test Rack?
We deploy a pre-compiled, closed-source libnccl-voltflow.so binary on a 32–64 GPU test cluster for a free 2-week validation trial.